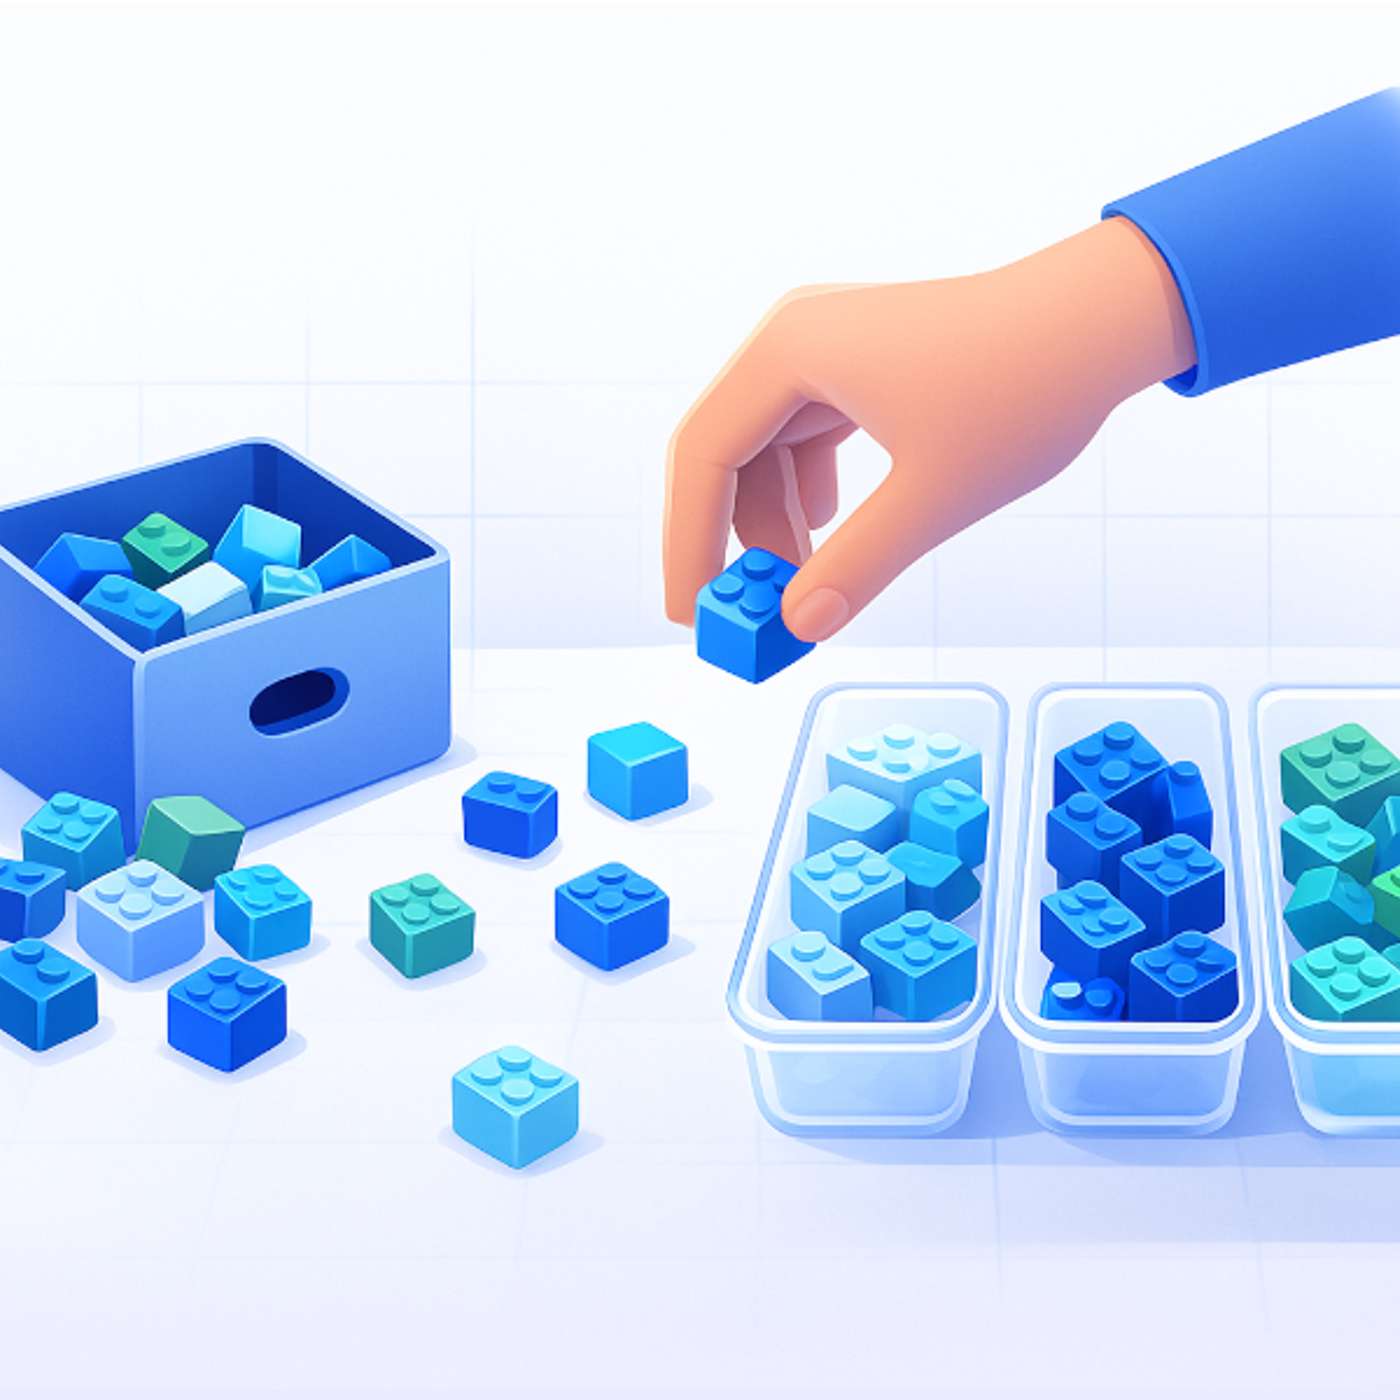
Building a Petabyte-Scale Web Archive
This story was originally published on HackerNoon at: https://hackernoon.com/building-a-petabyte-scale-web-archive . How we cut AWS costs after a $100,000 data retrieval mistake by optimizing our Web Archive. Check more stories related to tech-stories at: https://hackernoon.com/c/tech-stories . You can also check exclusive content about #web-archive-architecture , #aws , #web-data , #aws-glacier-costs , #etl-pipeline-optimization , #cost-efficient-data-pipelines , #bright-data-web-archive , #good-company , and more. This story was written by: @brightdata . Learn more about this writer by checking @brightdata's about page, and for more stories, please visit hackernoon.com . Discover how Bright Data optimize its Web Archive to handle petabytes of data in AWS. Learn how a $100,000 billing mistake revealed the trade-off between write speed, read speed, and cloud costs—and how we fixed it with a cost-effective Rearrange Pipeline. Spoiler: We are hiring!
You May Also Like

Jack Hopkins
Jack Hopkins
Search Engine
PJ Vogt

Jak Piggott
Jak Piggott
硅谷101
硅谷101

AI Fire Daily
AIFire.co

The Daily AI Show
The Daily AI Show Crew - Brian, Beth, Jyunmi, Andy and Karl
Tech&Co, la quotidienne
BFM Business

The AI Daily Brief: Artificial Intelligence News and Analysis
Nathaniel Whittemore
TBPN
John Coogan & Jordi Hays

The Vergecast
The Verge
Jack Hopkins
Jack Hopkins
Search Engine
PJ Vogt
Jak Piggott
Jak Piggott
硅谷101
硅谷101
AI Fire Daily
AIFire.co
The Daily AI Show
The Daily AI Show Crew - Brian, Beth, Jyunmi, Andy and Karl
Tech&Co, la quotidienne
BFM Business
The AI Daily Brief: Artificial Intelligence News and Analysis
Nathaniel Whittemore
TBPN
John Coogan & Jordi Hays
The Vergecast
The Verge
Community discussion