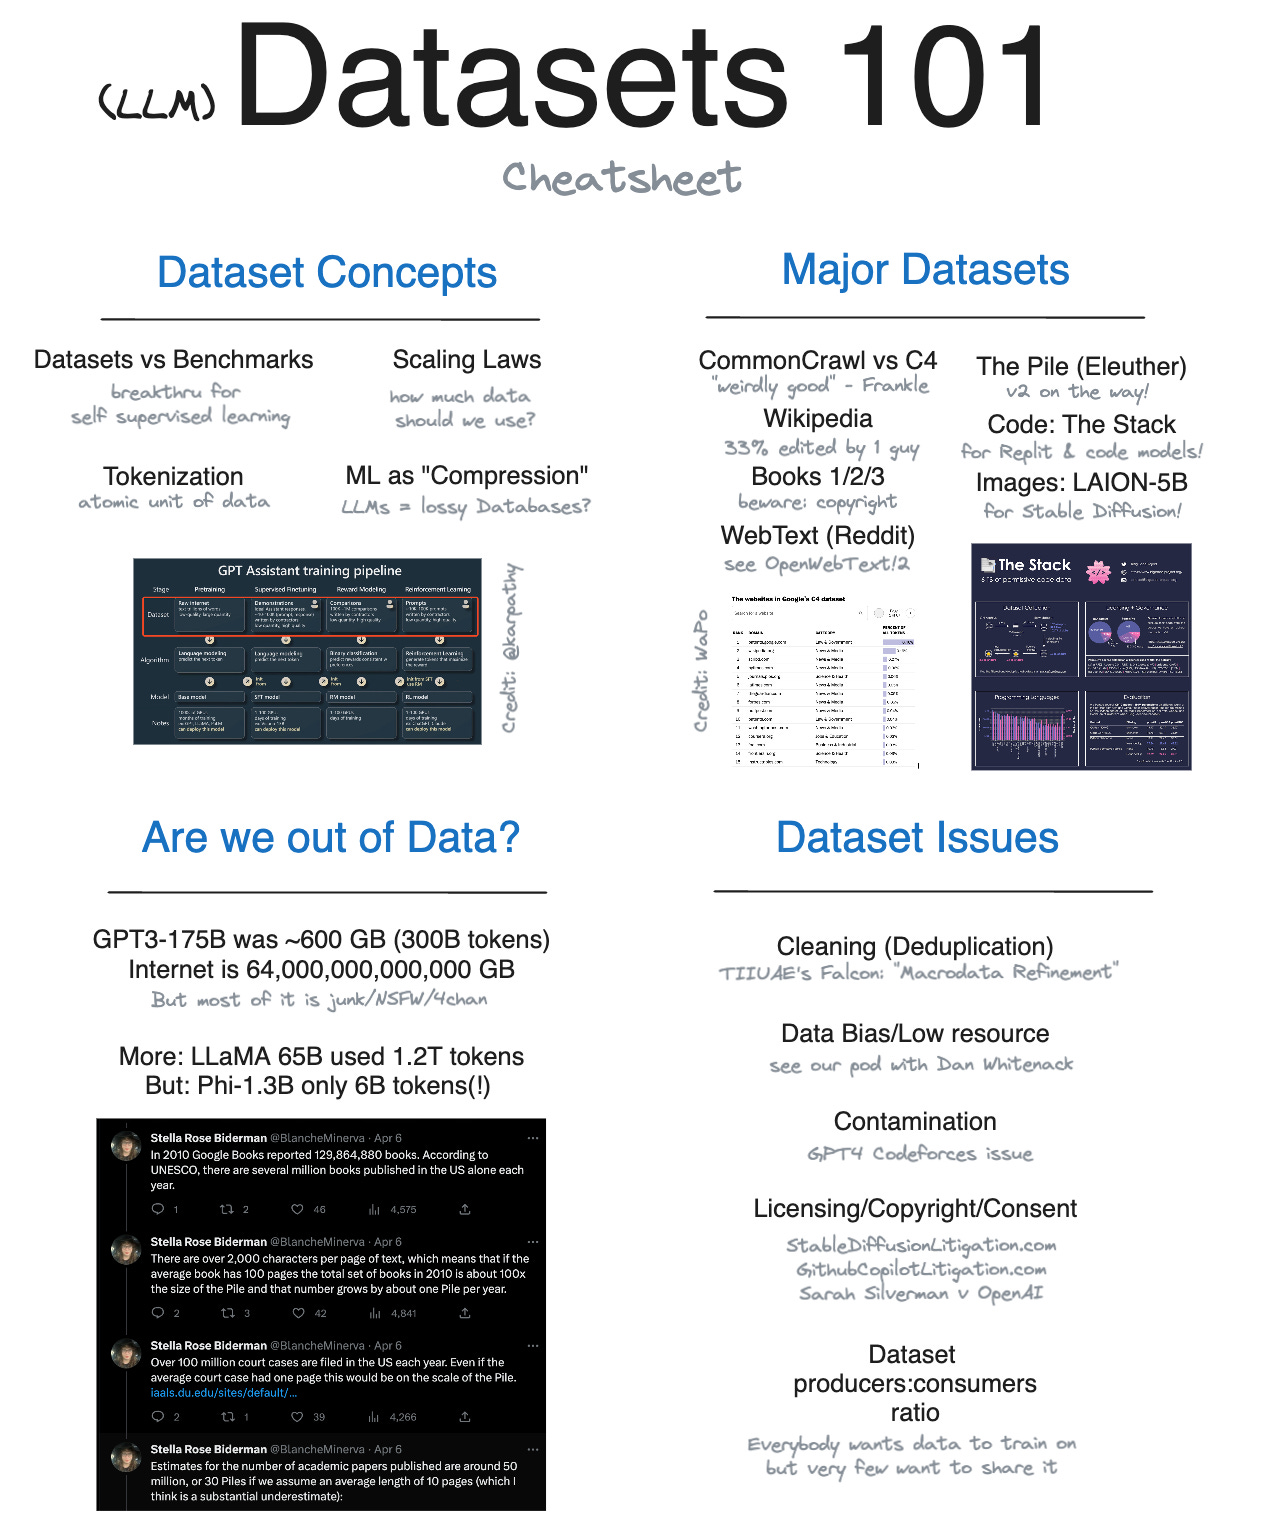
AI Fundamentals: Datasets 101
In April, we released our first AI Fundamentals episode: Benchmarks 101. We covered the history of benchmarks, why they exist, how they are structured, and how they influence the development of artificial intelligence.
Today we are (finally!) releasing Datasets 101! We’re really enjoying doing this series despite the work it takes - please let us know what else you want us to cover!
Stop me if you’ve heard this before: “GPT3 was trained on the entire Internet”.
Blatantly, demonstrably untrue: the GPT3 dataset is a little over 600GB, primarily on Wikipedia, Books corpuses, WebText and 2016-2019 CommonCrawl. The Macbook Air I am typing this on has more free disk space than that. In contrast, the “entire internet” is estimated to be 64 zetabytes, or 64 trillion GB. So it’s more accurate to say that GPT3 is trained on 0.0000000001% of the Internet.
Why spend $5m on GPU time training on $50 worth of data?
Simple: Garbage in, garbage out. No matter how good your algorithms, no matter how much money/compute you have, your model quality is strongly determined by the data you train it on and research scientists think we just don’t need or have that much high quality data. We spend an enormous amount of effort throwing out data to keep the quality high, and recently Web 2.0-era UGC platforms like StackOverflow, Reddit, and Twitter clamped down on APIs as they realize the goldmines they sit on.
Data is the new new oil. Time for a primer!
Show Notes
* Our 2 months worth of podcast prep notes!
* Karpathy’s Build Conference Presentation
* Phi-1 by Microsoft
* Washington Post Article on datasets
* Our episode with Jonathan Frankle
* Our episode with Mike Conover
* Datasets
* C4
* List of Dirty, Naughty, Obscene, and Otherwise Bad Words
* books3
* The Pile
* LAION
* Audio:
* LibriSpeech: A dataset of audio recordings of audiobooks
* CommonVoice: A dataset of audio recordings of people speaking different languages
* Voxforge: A dataset of audio recordings of people speaking different languages
* Switchboard: A dataset of audio recordings of telephone conversations
* Fisher Corpus: A dataset of audio recordings of news broadcasts
* Chinese:
* CMRC (Chinese Machine Reading Comprehension 2018)
* DuReader
* ChID
* Copyright & Privacy:
* https://stablediffusionlitigation.com/
* https://haveibeentrained.com/
* https://githubcopilotlitigation.com/
* https://twitter.com/moyix/status/1662131770463072257
* Check if you’re in The Stack
* Deduplication
* Deduplicating Training Data Makes Language Models Better
* Deduplicating Training Data Mitigates Privacy Risks in Language Models
* Contamination
This is a public episode. If you'd like to discuss this with other subscribers or get access to bonus episodes, visit www.latent.space/subscribe
You May Also Like

Theo - t3․gg
Theo - t3․gg

All-In with Chamath, Jason, Sacks & Friedberg
All-In Podcast, LLC

Artificial Intelligence Masterclass
AI Masterclass

The Daily AI Show
The Daily AI Show Crew - Brian, Beth, Jyunmi, Andy and Karl

CriptoMonedas TV
CriptoMonedas TV

Jack Hopkins
Jack Hopkins
MacMagazine no Ar
MacMagazine.com.br
AI Unraveled: Latest AI News & Trends, ChatGPT, Gemini, DeepSeek, Gen AI, LLMs, Agents, Ethics, Bias
Etienne Noumen
AI News Daily
brief.news

Security Weekly Podcast Network (Audio)
Security Weekly Productions
Theo - t3․gg
Theo - t3․gg
All-In with Chamath, Jason, Sacks & Friedberg
All-In Podcast, LLC
Artificial Intelligence Masterclass
AI Masterclass
The Daily AI Show
The Daily AI Show Crew - Brian, Beth, Jyunmi, Andy and Karl
CriptoMonedas TV
CriptoMonedas TV
Jack Hopkins
Jack Hopkins
MacMagazine no Ar
MacMagazine.com.br
AI Unraveled: Latest AI News & Trends, ChatGPT, Gemini, DeepSeek, Gen AI, LLMs, Agents, Ethics, Bias
Etienne Noumen
AI News Daily
brief.news
Security Weekly Podcast Network (Audio)
Security Weekly Productions
Community discussion