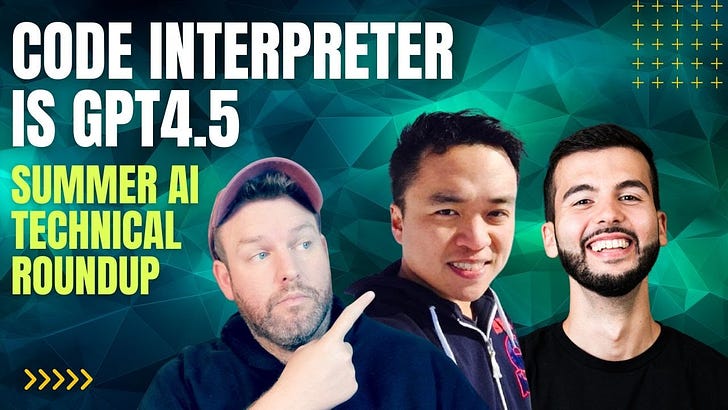
[AI Breakdown] Summer AI Technical Roundup: a Latent Space x AI Breakdown crossover pod!
Our 3rd podcast feed swap with other AI pod friends! Check out Cognitive Revolution and Practical AI as well.
NLW is the best daily AI YouTube/podcaster with the AI Breakdown. His summaries and content curation are spot on and always finds the interesting angle that will keep you thinking. Subscribe to the AI Breakdown wherever fine podcasts are sold! https://pod.link/1680633614
You can also watch on YouTube:
Timestamps
The hosts discuss the launch of Code Interpreter as a separate model from OpenAI and speculate that it represents the release of GPT 4.5. People have found Code Interpreter to be better than expected, even for tasks unrelated to coding. They discuss the significance of this release, as well as the challenges of evaluating AI models, the cultural mismatch between researchers and users, and the increasing value of data in the AI industry. They also touch on the impact of open-source tools, the potential of AI companions, the advantages of Anthropics compared to other platforms, advancements in image recognition and multimodality, and predictions for the future of AI.
* 00:00:00 In this section, the hosts discuss the launch of Code Interpreter from OpenAI and its significance in the development of the AI field. They explain that Code Interpreter, initially introduced as a plugin, is now considered a separate model with its own dropdown menu. They note that people have found Code Interpreter to be better than expected, even for tasks that are not related to coding. This leads them to speculate that Code Interpreter actually represents the release of GPT 4.5, as there has been no official announcement or blog post about it. They also mention that the AI safety concerns and regulatory environment may be impacting how OpenAI names and labels their models. Overall, they believe that Code Interpreter's release signifies a significant shift in the AI field and hints at the possibility of future advanced models like GPT 5.
* 00:05:00 In this section, the speaker discusses the improvements in GPT 4.5 and how it enhances the experience for non-coding queries and inputs. They explain that the code interpreter feature allows for a wider range of use cases that were not possible with previous models like GPT 3.5. Additionally, they highlight the value of the code interpreter in assisting individuals with no coding experience to solve basic coding problems. This feature is likened to having a junior developer or intern analyst that aids in conducting tests and simplifies coding tasks. The speaker emphasizes that GPT 4.5 enables users to be more productive and efficient, especially when dealing with code-related challenges. They also discuss the future direction of AGI, where more time will be dedicated to inference rather than training, as this approach has shown significant improvements in terms of problem-solving.
* 00:10:00 In this section, the speaker discusses how advanced AI models like GPT-4.5 are not just larger versions of previous models but rather employ fundamentally different techniques. They compare the evolution of AI models to the evolutionary timeline of humans, where the invention of tools opened up a whole new set of possibilities. They touch on the difficulty of evaluating AI models, particularly in more subjective tasks, and highlight how perceptions of model performance can be influenced by factors like formatting preferences. Additionally, the speaker mentions the challenges of reinforcement learning and the uncertainty around what the model is prioritizing in its suggestions. They conclude that OpenAI, as a research lab, is grappling with the complexities of updating models and ensuring reliability for users.
* 00:15:00 In this section, the speaker discusses the cultural mismatch between OpenAI researchers and users of OpenAI's products, highlighting the conflicting statements made about model updates. They suggest that OpenAI needs to establish a policy that everyone can accept. The speaker also emphasizes the challenges of communication and the difficulty of serving different stakeholders. They mention the impact of small disruptions on workflows and the lack of immediate feedback within OpenAI's system. Additionally, the speaker briefly discusses the significance of OpenAI's custom instructions feature, stating that it allows for more personalization but is not fundamentally different from what other chat companies already offer. The discussion then transitions to Facebook's release of LAMA2, which holds significance both technically and for users, although further details on its significance are not provided in this excerpt.
* 00:20:00 In this section, the introduction of GPT-4.5, also known as LAVA 2, is discussed. LAVA 2 is the first fully commercially usable GPT 3.5 equivalent model, which is a significant development because it allows users to run it on their own infrastructure and fine-tune it according to their needs. Although it is not fully open source, it presents new opportunities for various industries such as government, healthcare, and finance. The discussion also touches upon the open source aspect of LAVA 2, with the recognition that it has still contributed significantly to the community, as evidenced by the three million dollars' worth of compute and the estimated 15 to 20 million dollars' worth of additional fine-tuning capabilities it brings. The conversation acknowledges the value of open source models and data, while also recognizing the challenges and complexities in striking a balance between openness and restrictions.-
* 00:25:00 In this section, the discussion centers around the commoditization of compute and the increasing value of data in the AI industry. While GPU compute is currently in high demand, it is observed that data is what holds the real value in AI. The conversation touches on the history of Open Source models and how the release of data for models like GPT J and GPT Neo signal a shift towards prioritizing data over model weights. The transcript also mentions the caution around data usage, citing examples of copyright concerns with datasets like Bookcorpus. The debate arises on whether ML engineers should proactively use open data or wait for permission, with some arguing for proactive usage to avoid holding back progress. The conversation also discusses the importance of terminology and protecting the definition of open source, while recognizing that the functional implications of open data are what matter most.
* 00:30:00 In this section, the conversation revolves around the impact of open-source tools on companies and how it has influenced their approach to AI development. It is noted that companies can no longer just offer a nice user interface (UI) wrapper around an open AI model, as customers are demanding more. The comp
You May Also Like

Jak Piggott
Jak Piggott

ゆるコンピュータ科学ラジオ
pedantic

User Friendly - The Podcast
User Friendly Productions

Artificial Intelligence Masterclass
AI Masterclass
Rich On Tech
iHeartPodcasts

Programmieren lernen - Der Developer Akademie Podcast
[email protected] (Developer Akademie)
The Deep Dive Radio Show and Nick's Nerd News
Nick Espinosa, Chief Security Fanatic

Mark Tilbury
Mark Tilbury Fan
RadioCSIRT
Marc Frédéric GOMEZ
The Good Tech Companies
HackerNoon
Jak Piggott
Jak Piggott
ゆるコンピュータ科学ラジオ
pedantic
User Friendly - The Podcast
User Friendly Productions
Artificial Intelligence Masterclass
AI Masterclass
Rich On Tech
iHeartPodcasts
Programmieren lernen - Der Developer Akademie Podcast
[email protected] (Developer Akademie)
The Deep Dive Radio Show and Nick's Nerd News
Nick Espinosa, Chief Security Fanatic
Mark Tilbury
Mark Tilbury Fan
RadioCSIRT
Marc Frédéric GOMEZ
The Good Tech Companies
HackerNoon
Community discussion