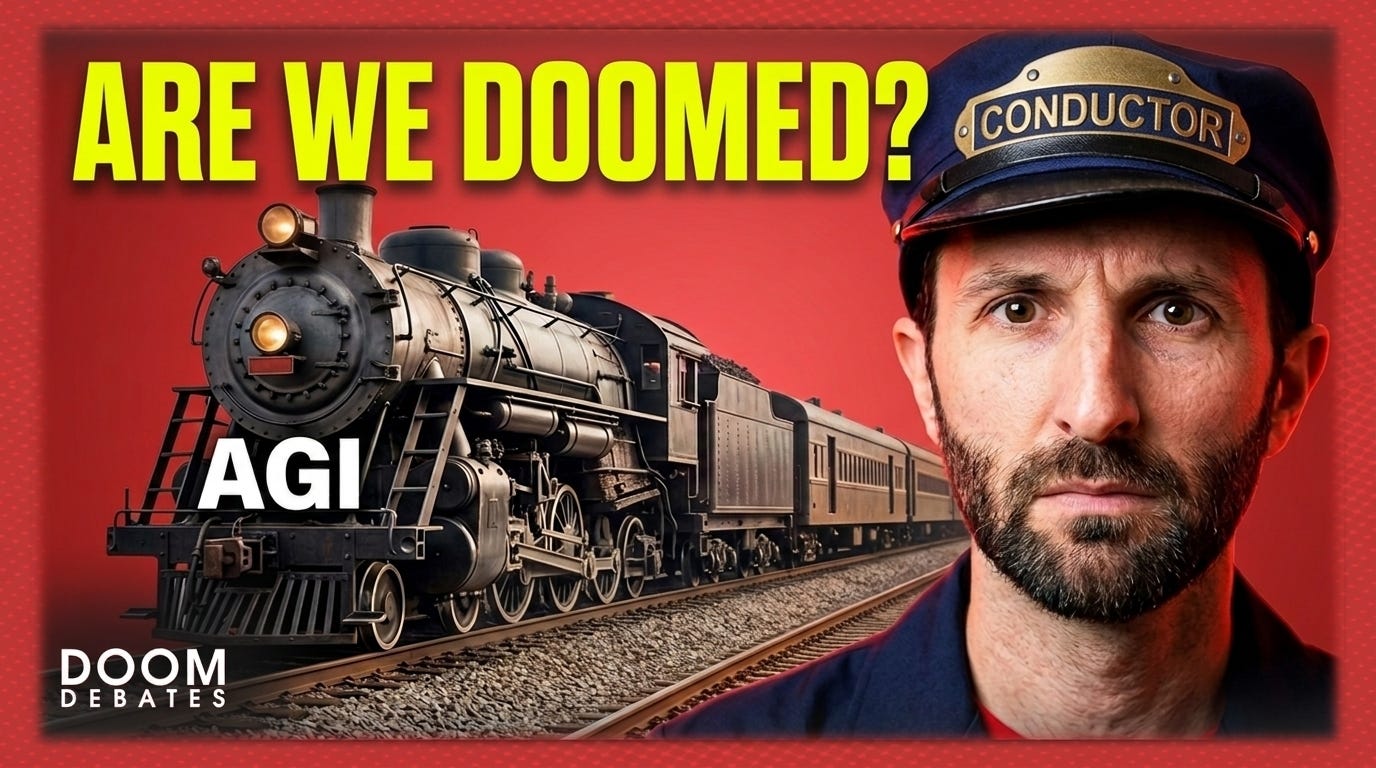
Where Do YOU Get Off the Doom Train? Live Debate at Manifest 2026
Producer Ori takes over hosting duties in this special episode, a live recording from Manifest 2026.
He takes attendees for a ride on The Doom Train, the series of claims involved in arguing that P(Doom) is high. Every stop is a place where people get off before reaching that conclusion.
The crowd at Manifest is a mix of forecasters, rationalists, and AI researchers with a wide range of P(Doom) positions. Even without me or Eliezer in the room, there are plenty of Yudkowskians to push back on the accelerationist claims.
Watch along and decide where YOU get off, or if you ride all the way to doomtown with us. Also, grab the Doom Train framework down below so you can get to the crux of disagreement in your own AI x-risk conversations.
Timestamps
00:00:00 — Cold Open
00:00:25 — Liron Introduces Producer Ori’s Manifest Session
00:02:30 — Previewing the Doom Train™ Stops
00:03:38 — Audience P(Doom) Poll
00:05:00 — Stop 1: AGI Isn’t Coming Soon
00:10:43 — Stop 2: AI Can’t Go Far Beyond Human Intelligence
00:15:05 — Stop 3: AI Won’t Be a Physical Threat
00:18:14 — Stop 4: Intelligence Yields Moral Goodness
00:21:38 — Will ASI Behave Because Alien ASIs Are Watching?
00:26:01 — Stop 5: We Have a Safe AI Development Process
00:28:33 — Stop 6: AI Capabilities Will Rise at a Manageable Pace
00:30:08 — Stop 7: AI Won’t Try to Conquer the Universe
00:34:22 — Stop 8: Superalignment Is a Tractable Problem
00:38:01 — Stop 9: Once We Solve Superalignment, We’ll Enjoy Peace
00:41:14 — Stop 10: Unaligned ASI Will Spare Us
00:47:35 — Stop 11: AI Doomerism Is Bad Epistemology
00:49:02 — Bonus Stops and Wrap-Up
The Doom Train Framework
Stops on the Doom Train
AGI isn’t coming soon
* No consciousness
* No emotions
* No creativity — AIs are limited to copying patterns in their training data, they can’t “generate new knowledge”
* AIs aren’t even as smart as dogs right now, never mind humans
* AIs constantly make dumb mistakes, they can’t even do simple arithmetic reliably
* LLM performance is hitting a wall — GPT 4.5 is barely better than GPT 4.1 despite being larger scale
* No genuine reasoning
* No microtubules exploiting uncomputable quantum effects
* No soul
* We’ll need to build tons of data centers and power before we get to AGI
* No agency
* This is just another AI hype cycle, every 25 years people think AGI is coming soon and they’re wrong
Artificial intelligence can’t go far beyond human intelligence
* “Superhuman intelligence” is a meaningless concept
* Human engineering already is coming close to the laws of physics
* Coordinating a large engineering project can’t happen much faster than humans do it
* No individual human is that smart compared to humanity as a whole, including our culture, corporations, and other institutions. Similarly no individual AI will ever be that smart compared to the sum of human culture and other institutions.
AI won’t be a physical threat
* AI doesn’t have arms or legs, it has zero control over the real world
* An AI with a robot body can’t fight better than a human soldier
* We can just disconnect an AI’s power to stop it
* We can just turn off the internet to stop it
* We can just shoot it with a gun
* It’s just math
* Any supposed chain of events where AI kills humans is far-fetched science fiction
Intelligence yields moral goodness
* More intelligence is correlated with more morality
* Smarter people commit fewer crimes
* The orthogonality thesis is false
* AIs will discover moral realism
* If we made AIs so smart, and we were trying to make them moral, then they’ll be smart enough to debug their own morality
* Positive-sum cooperation was the outcome of natural selection
We have a safe AI development process
* Just like every new technology, we’ll figure it out as we go
* We don’t know what problems need to be fixed until we build the AI and test it out
* If an AI causes problems, we’ll be able to turn it off and release another version
* We have safeguards to make sure AI doesn’t get uncontrollable/unstoppable
* If we accidentally build an AI that stops accepting our shutoff commands, it won’t manage to copy versions of itself outside our firewalls which then proceed to spread exponentially like a computer virus
* If we accidentally build an AI that escapes our data center and spreads exponentially like a computer virus, it won’t do too much damage in the world before we can somehow disable or neutralize all its copies
* If we can’t disable or neutralize copies of rogue AIs, we’ll rapidly build other AIs that can do that job for us, and won’t themselves go rogue on us
AI capabilities will rise at a manageable pace
* Building larger data centers will be a speed bottleneck
* Another speed bottleneck is the amount of research that needs to be done, both in terms of computational simulation, and in terms of physical experiments, and this kind of research takes lots of time
* Recursive self-improvement “foom” is impossible
* The whole economy never grows with localized centralized “foom”
* Need to collect cultural learnings over time, like humanity did as a whole
* AI is just part of the good pattern of exponential economic growth eras
AI won’t try to conquer the universe
* AIs can’t “want” things
* AIs won’t have the same “fight instincts” as humans and animals, because they weren’t shaped by a natural selection process that involved life-or-death resource competition
* Smart employees often work for less-smart bosses
* Just because AIs help achieve goals doesn’t mean they have to be hard-core utility maximizers
* Instrumental convergence is false: achieving goals effectively doesn’t mean you have to be relentlessly seizing power and resources
* A resource-hungry goal-maximizer AIs wouldn’t seize literally every atom; there’ll still be some leftover resources for humanity
* AIs will use new kinds of resources that humans aren’t using - dark energy, wormholes, alternate universes, etc
Superalignment is a tractable problem
* Current AIs have never killed anybody
* Current AIs are extremely successful at doing useful tasks for humans
* If AIs are trained on data from humans, they’ll be “aligned by default”
* We can just make AIs abide by our laws
* We can align the superintelligent AIs by using a scheme involving cryptocurrency on the blockchain
* Companies have economic incentives to solve superintelligent AI alignment, because unaligned superintelligent AI would hurt their profits
* We’ll build an aligned not-that-smart AI, which will figure out how to build the next-generation AI which is smarter and still aligned to human values, and so on until aligned superintelligence
Once we solve superalignment, we’ll enjoy peace
* The power from ASI won’t be monopolized by a single human government / tyranny
* The decentralized nodes of human-ASI hybrids won’t be like warlords constantly fighting each other, they’ll be like countries making peace
* Defense will have an advantage over attack, so the equilibrium of all the groups of humans and ASIs will be multiple defended regions, not a war of mutual destruction
* The world of human-owned ASIs is a stable equilibrium, not one where ASI-focused projects keep buying out and taking resources away from human-focused ones (Gradual Disempowerment)
Unaligned ASI will spare us
You May Also Like

Theo - t3․gg
Theo - t3․gg

TBPN
John Coogan & Jordi Hays
Applelianos
Applelianos

Security Weekly Podcast Network (Audio)
Security Weekly Productions

RadioCSIRT
Marc Frédéric GOMEZ

Engadget News + Next
Engadget

The Daily AI Show
The Daily AI Show Crew - Brian, Beth, Jyunmi, Andy and Karl
TechCheck
CNBC
Tech Life
BBC World Service

Elon Musk Podcast
Stage Zero
Theo - t3․gg
Theo - t3․gg
TBPN
John Coogan & Jordi Hays
Applelianos
Applelianos
Security Weekly Podcast Network (Audio)
Security Weekly Productions
RadioCSIRT
Marc Frédéric GOMEZ
Engadget News + Next
Engadget
The Daily AI Show
The Daily AI Show Crew - Brian, Beth, Jyunmi, Andy and Karl
TechCheck
CNBC
Tech Life
BBC World Service
Elon Musk Podcast
Stage Zero
Community discussion